I am an undergraduate student in Mathematics & Applied Mathematics at the University of Nottingham Ningbo China. My work sits at the intersection of mathematical foundations and practical machine learning systems.
My primary research affiliation is with the Di² Lab at HKUST(GZ), where I work on text-to-motion generation and embodied AI under the supervision of Associate Professor Yutao YUE. I also work remotely on QuantVLA, quantization for efficient Vision-Language-Action models, jointly supervised by Assistant Professor Xiao Luo at the University of Wisconsin–Madison and Assistant Professor Yiyang Gu at the Beijing Zhongguancun Academy. Previously, at the Shenzhen University of Advanced Technology, I worked on token-efficient gigapixel pathology reasoning and developed TC-SSA.
You can find my publications on Google Scholar. Total citations: -.
🔥 News
- 2026.08: 📦 Released the TC-SSA dataset on Hugging Face.
- 2026.08: 🌐 Started working on QuantVLA as a Remote Research Assistant, jointly supervised by Assistant Professor Xiao Luo (University of Wisconsin–Madison) and Assistant Professor Yiyang Gu (Beijing Zhongguancun Academy).
- 2026.06: 🚀 Joined Di² Lab at HKUST(GZ) as a Research Assistant, supervised by Associate Professor Yutao YUE.
- 2026.06: 🎉🎉 Our paper TC-SSA: Token Compression via Semantic Slot Aggregation was accepted to MICCAI 2026!
- 2026.06: 📄 SparseLearn: Learnable Token Pruning with Continuous Noise Gating for Gigapixel Whole-Slide Images is now available on arXiv and is under review at WACV.
- 2026.03: 📄 TC-SSA: Token Compression via Semantic Slot Aggregation was released on arXiv.
- 2025.07: 🔬 Joined the Computer Vision and Recognition Center (AI觉-知研究中心) at Shenzhen University of Advanced Technology as a Research Assistant.
📝 Publications
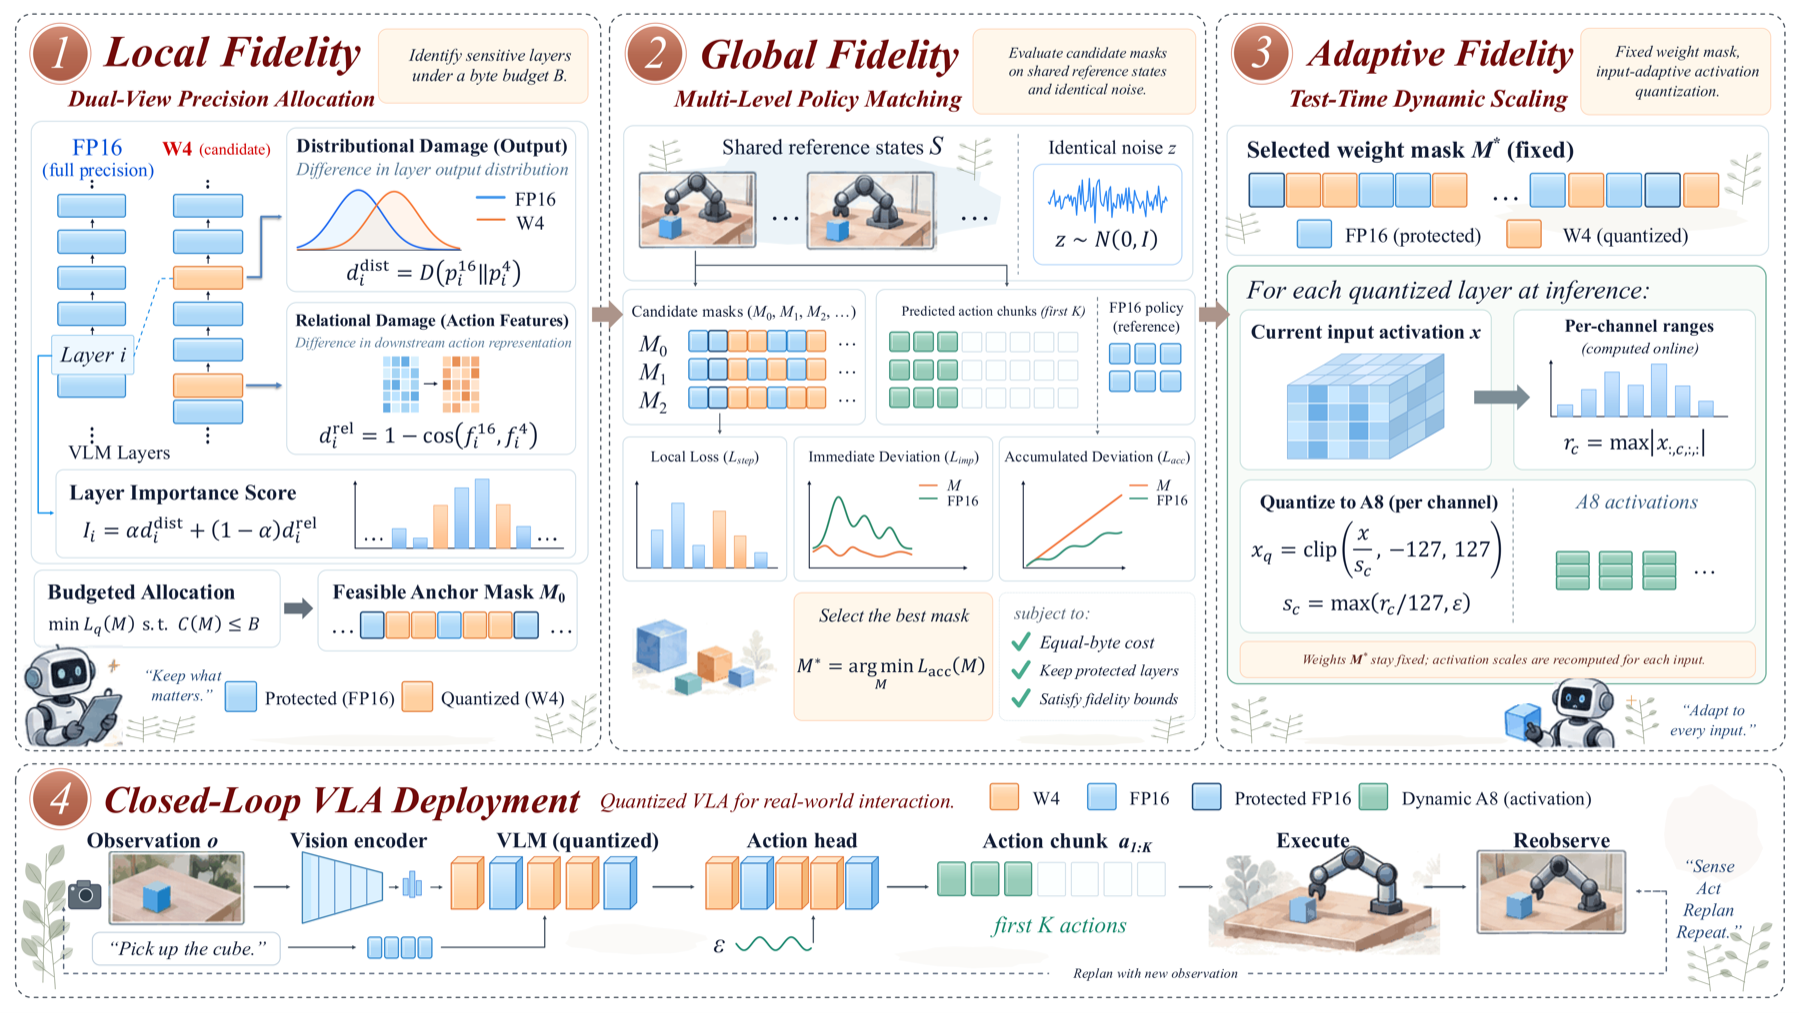
TriFiQ: Tri-Fidelity Quantization for Vision-Language-Action Models
University of Wisconsin–Madison & Beijing Zhongguancun Academy
- Local fidelity: scores each VLM layer by the distributional damage to its outputs and the relational damage to downstream action features, then allocates FP16 protection under a byte budget.
- Global fidelity: evaluates candidate precision masks by multi-level policy matching against the FP16 policy on shared reference states with identical noise, using step, immediate, and accumulated deviations of the predicted action chunks.
- Adaptive fidelity: keeps the selected weight mask fixed and quantizes activations to A8 with per-channel ranges computed online for each input, enabling closed-loop deployment of the quantized VLA.
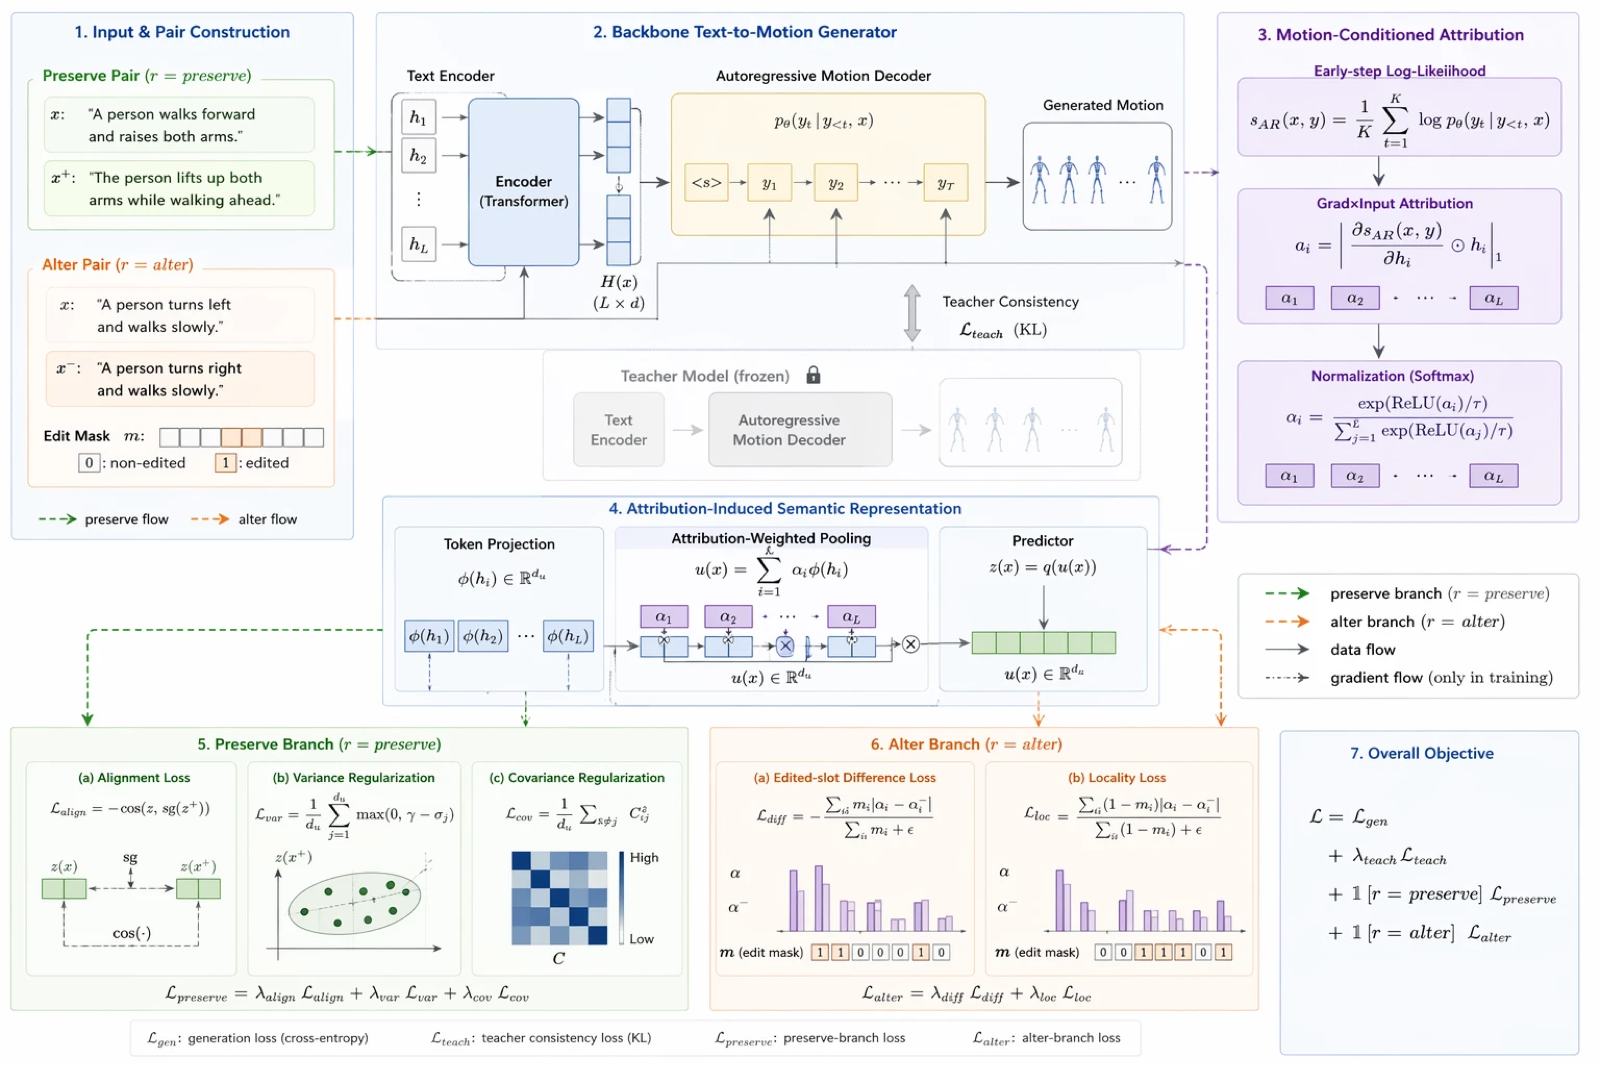
Compass: Attribution-Induced Semantic Representations for Text-to-Motion Generation
HKUST(GZ) — Di² Lab
- Attributes an autoregressive text-to-motion generator’s early-step log-likelihood back to text tokens with Grad×Input, yielding motion-conditioned token weights.
- Pools token projections with these attribution weights into a semantic representation and trains it with preserve pairs (alignment plus variance and covariance regularization) and alter pairs (edited-slot difference and locality losses on the edit mask).
- Keeps the backbone generator faithful through a KL consistency loss against a frozen teacher while the attribution-induced representation is learned.
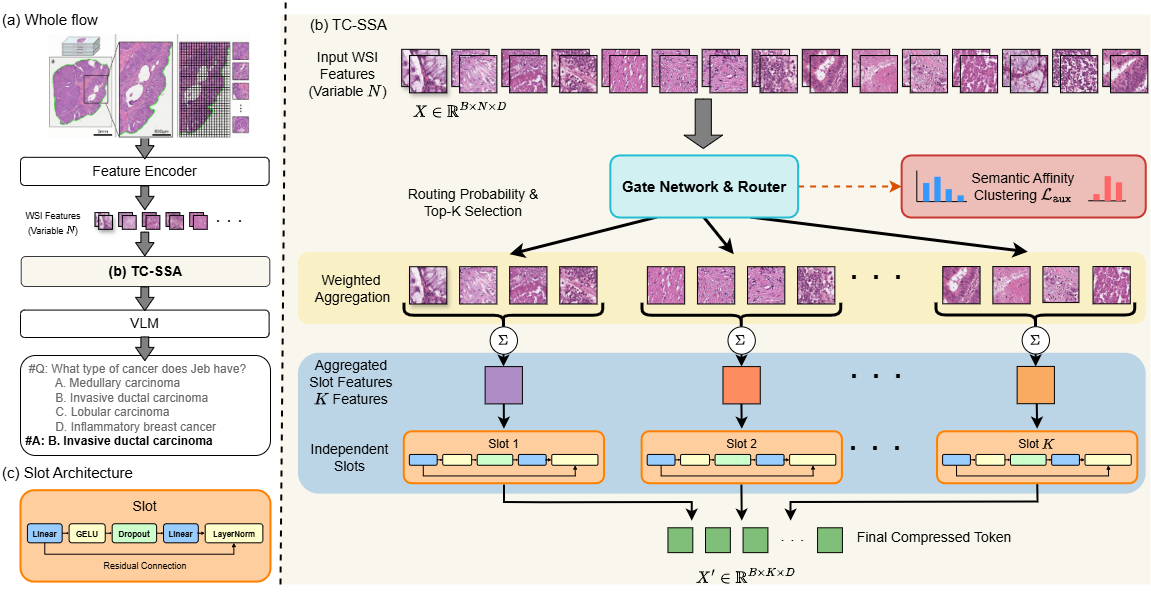
TC-SSA: Token Compression via Semantic Slot Aggregation for Gigapixel Pathology Reasoning
Zhuo Chen, Xiaoyu Yang, Lijian Xu
📦 Dataset · Total downloads: -
- Aggregates all WSI patch features into a fixed budget of 32 semantic slots through sparse Top-2 routing.
- Retains global slide evidence with only 1.7% of the original visual tokens and 1.72T FLOPs.
- Achieves 78.34% overall accuracy and 77.14% diagnosis accuracy on SlideBench (TCGA).
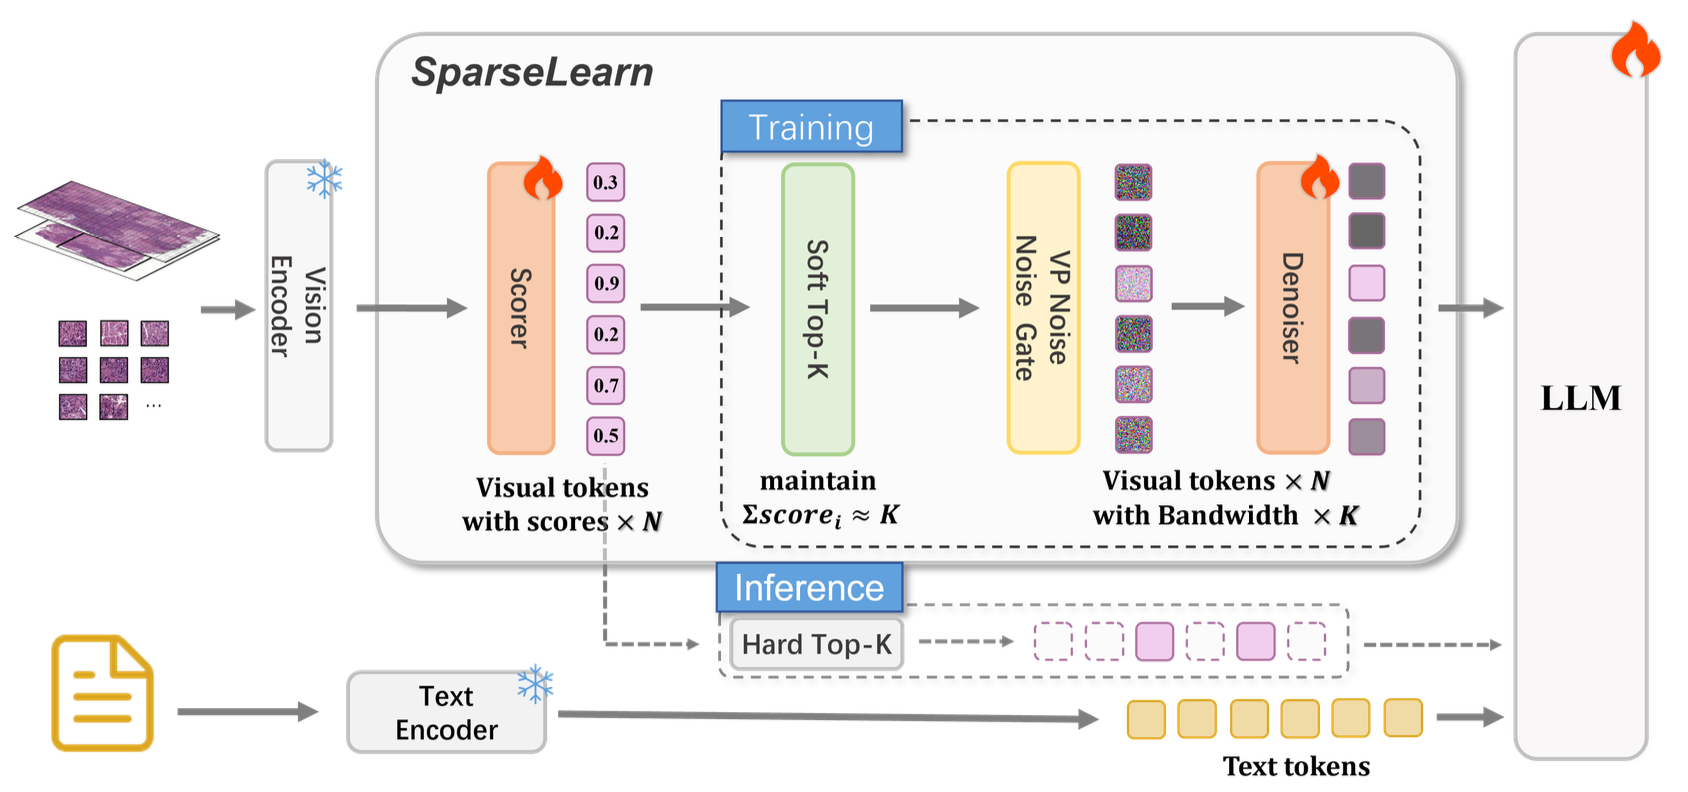
SparseLearn: Learnable Token Pruning with Continuous Noise Gating for Gigapixel Whole-Slide Images
- Learnable token pruning for gigapixel WSI reasoning: a lightweight scorer is optimized end-to-end from downstream supervision instead of relying on training-free spatial sampling.
- During training, a differentiable Soft Top-K turns scores into continuous token weights that gate variance-preserving noise injection, and a diagonal-attention denoiser recovers the features without cross-token leakage.
- At inference the gating and denoiser are removed and a deterministic Hard Top-K keeps just 32 visual tokens, a 128× reduction from the 4,096-token context, reaching 73.32% overall accuracy on SlideBench (TCGA) versus 74.81% for the unpruned SlideChat baseline, with competitive zero-shot results on SlideBench (BCNB) and WSI-VQA.
- Preprint: arXiv:2606.08641.
💻 Research Experience
B.Sc. in Mathematics & Applied Mathematics
University of Nottingham
- Relevant Coursework: Linear Algebra, Machine Learning, Deep Learning, Computer Vision.
Research Assistant
Shenzhen University of Advanced Technology — AI Center (Computer Vision and Recognition Center)
Under the supervision of Associate Professor Lijian Xu
- Developed TC-SSA, a semantic-slot token compression framework for efficient gigapixel whole-slide image reasoning.
- Compressed thousands of pathology patch tokens into 32 semantic slots while preserving global slide-level evidence.

Research Assistant
HKUST(GZ) — Di² Lab
Under the supervision of Associate Professor Yutao YUE
- Conducting research on text-to-motion generation and human motion synthesis from natural-language instructions.
- Exploring embodied AI systems that connect multimodal perception, language understanding, and action generation.
Remote Research Assistant
University of Wisconsin–Madison — Department of Statistics & Beijing Zhongguancun Academy
Jointly supervised by Assistant Professor Xiao Luo (UW–Madison) and Assistant Professor Yiyang Gu (Beijing Zhongguancun Academy)
- Working on QuantVLA: quantization of Vision-Language-Action models for efficient robot policies.
- Investigating post-training quantization and memory-efficient deployment for embodied AI systems.